DISTILLATIONSMALL LMS
Teach the small model the teacher's ranking, not its probabilities.
Keep the teacher's preferences. Drop its confidence.
Read the slides as text 6 slides
Slide 1 · DISTILLATION · SMALL LMS
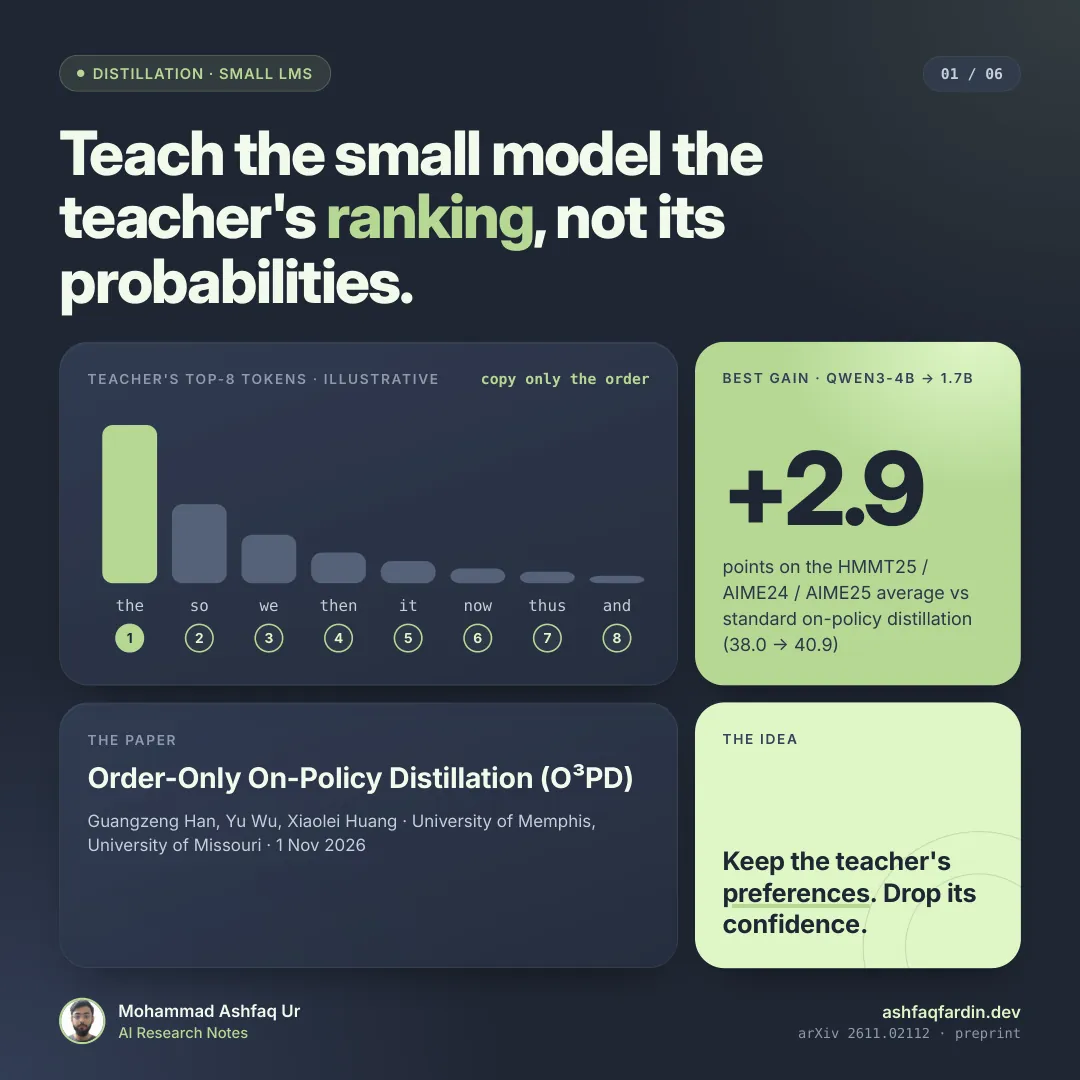
Teach the small model the teacher's ranking, not its probabilities.
TEACHER'S TOP-8 TOKENS · ILLUSTRATIVE
copy only the order
the 1 so 2 we 3 then 4 it 5 now 6 thus 7 and 8
BEST GAIN · QWEN3-4B → 1.7B
+2.9
points on the HMMT25 / AIME24 / AIME25 average vs standard on-policy distillation (38.0 → 40.9)
THE PAPER
Order-Only On-Policy Distillation (O³PD)
Guangzeng Han, Yu Wu, Xiaolei Huang · University of Memphis, University of Missouri · 1 Nov 2026
THE IDEA
Keep the teacher's preferences. Drop its confidence.
Slide 2 · THE PROBLEM
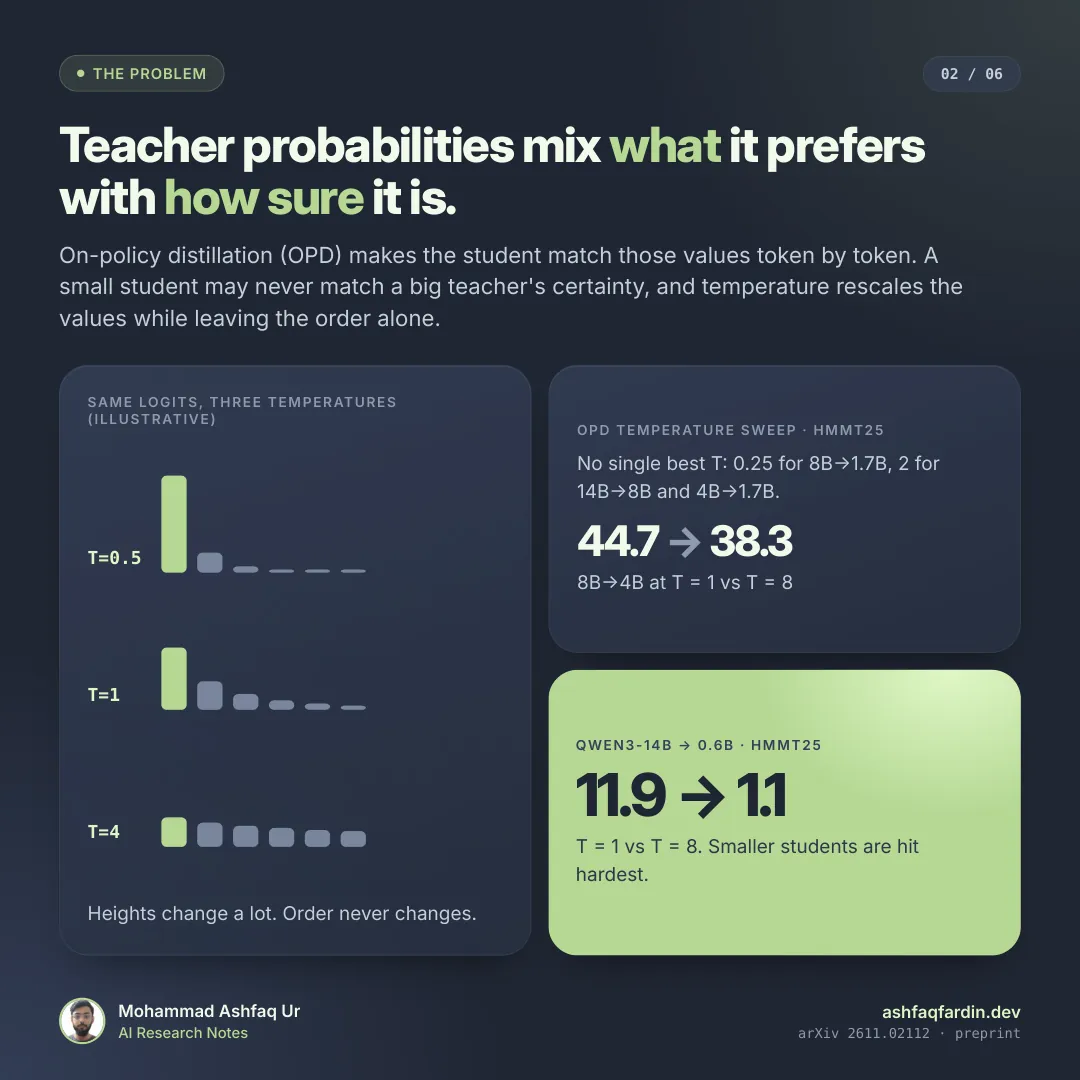
Teacher probabilities mix what it prefers with how sure it is.
On-policy distillation (OPD) makes the student match those values token by token. A small student may never match a big teacher's certainty, and temperature rescales the values while leaving the order alone.
SAME LOGITS, THREE TEMPERATURES (ILLUSTRATIVE)
T=0.5 T=1 T=4
Heights change a lot. Order never changes.
OPD TEMPERATURE SWEEP · HMMT25
No single best T: 0.25 for 8B→1.7B, 2 for 14B→8B and 4B→1.7B.
44.7 → 38.3
8B→4B at T = 1 vs T = 8
QWEN3-14B → 0.6B · HMMT25
11.9 → 1.1
T = 1 vs T = 8. Smaller students are hit hardest.
Slide 3 · THE METHOD · O³PD
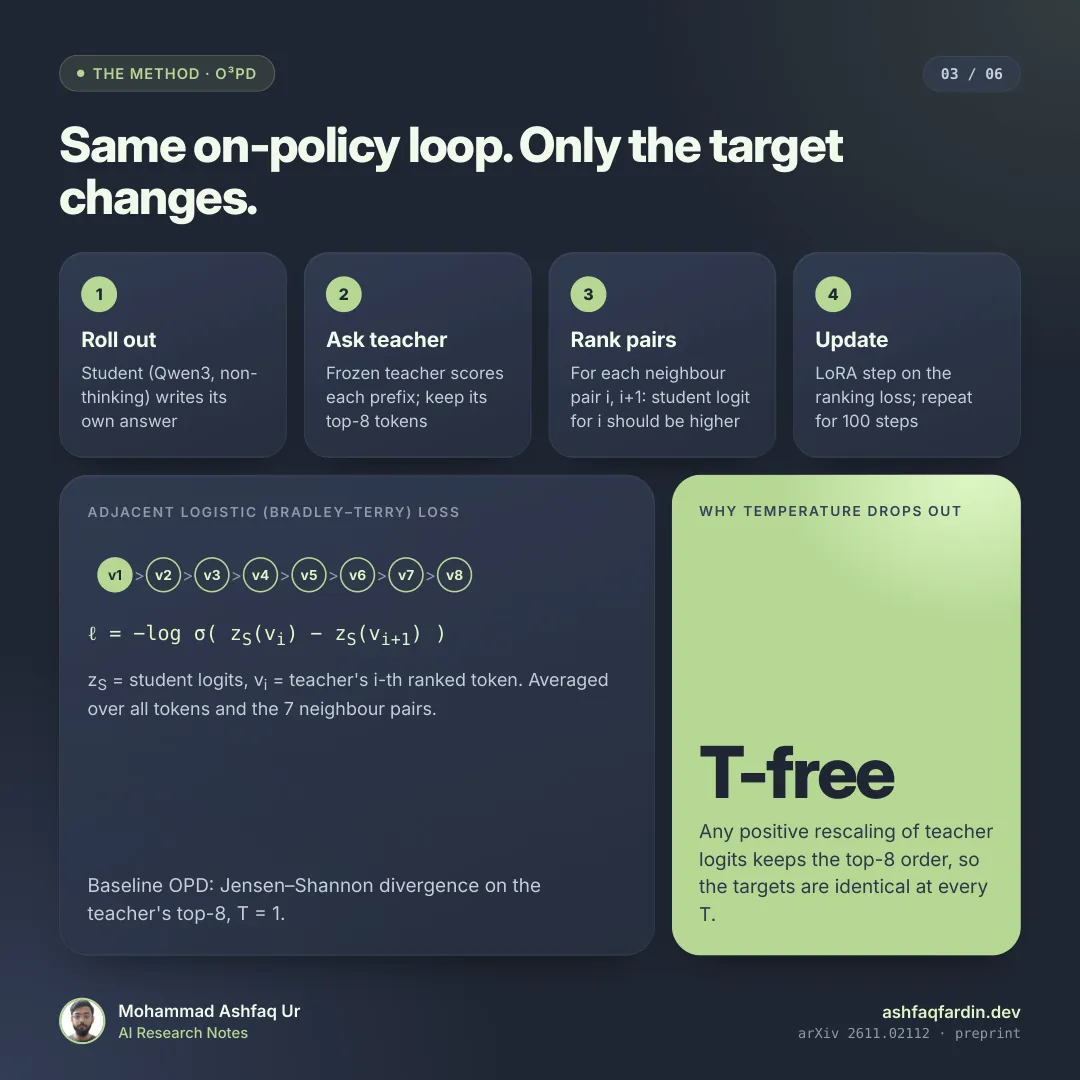
Same on-policy loop. Only the target changes.
1 Roll out
Student (Qwen3, non- thinking) writes its own answer
2 Ask teacher
Frozen teacher scores each prefix; keep its top-8 tokens
3 Rank pairs
For each neighbour pair i, i+1: student logit for i should be higher
4 Update
LoRA step on the ranking loss; repeat for 100 steps
ADJACENT LOGISTIC (BRADLEY–TERRY) LOSS
v1 > v2 > v3 > v4 > v5 > v6 > v7 > v8
ℓ = −log σ( zS(vi) − zS(vi+1) )
zS = student logits, vi = teacher's i-th ranked token. Averaged over all tokens and the 7 neighbour pairs.
Baseline OPD: Jensen–Shannon divergence on the teacher's top-8, T = 1.
WHY TEMPERATURE DROPS OUT
T-free
Any positive rescaling of teacher logits keeps the top-8 order, so the targets are identical at every T.
Slide 4 · KEY RESULT
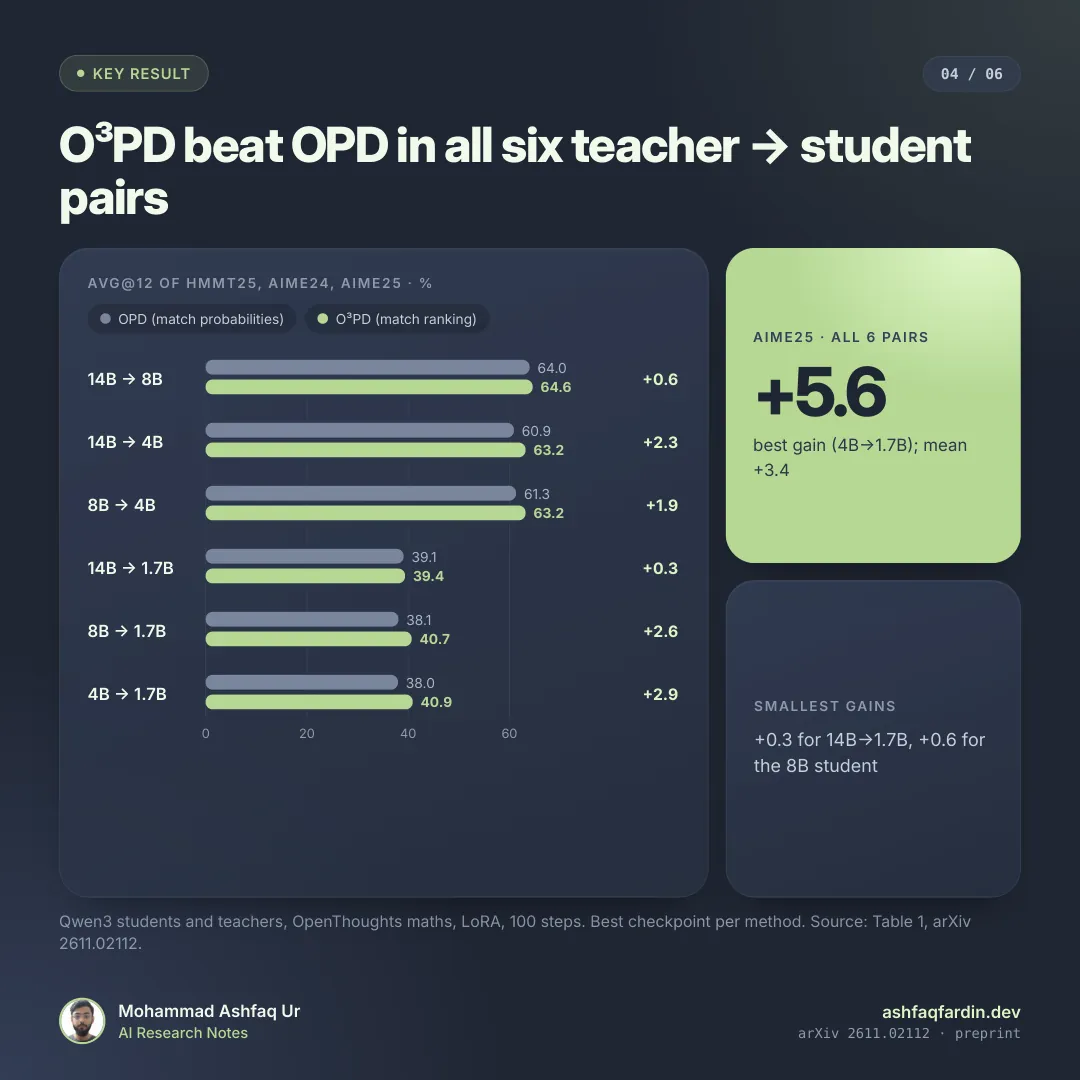
O³PD beat OPD in all six teacher → student pairs
Qwen3 students and teachers, OpenThoughts maths, LoRA, 100 steps. Best checkpoint per method. Source: Table 1, arXiv 2611.02112.
AVG@12 OF HMMT25, AIME24, AIME25 · %
OPD (match probabilities)
O³PD (match ranking)
0 20 40 60 14B → 8B 64.0 64.6 +0.6 14B → 4B 60.9 63.2 +2.3 8B → 4B 61.3 63.2 +1.9 14B → 1.7B 39.1 39.4 +0.3 8B → 1.7B 38.1 40.7 +2.6 4B → 1.7B 38.0 40.9 +2.9
AIME25 · ALL 6 PAIRS
+5.6
best gain (4B→1.7B); mean +3.4
SMALLEST GAINS
+0.3 for 14B→1.7B, +0.6 for the 8B student
Slide 5 · WHY IT WORKS
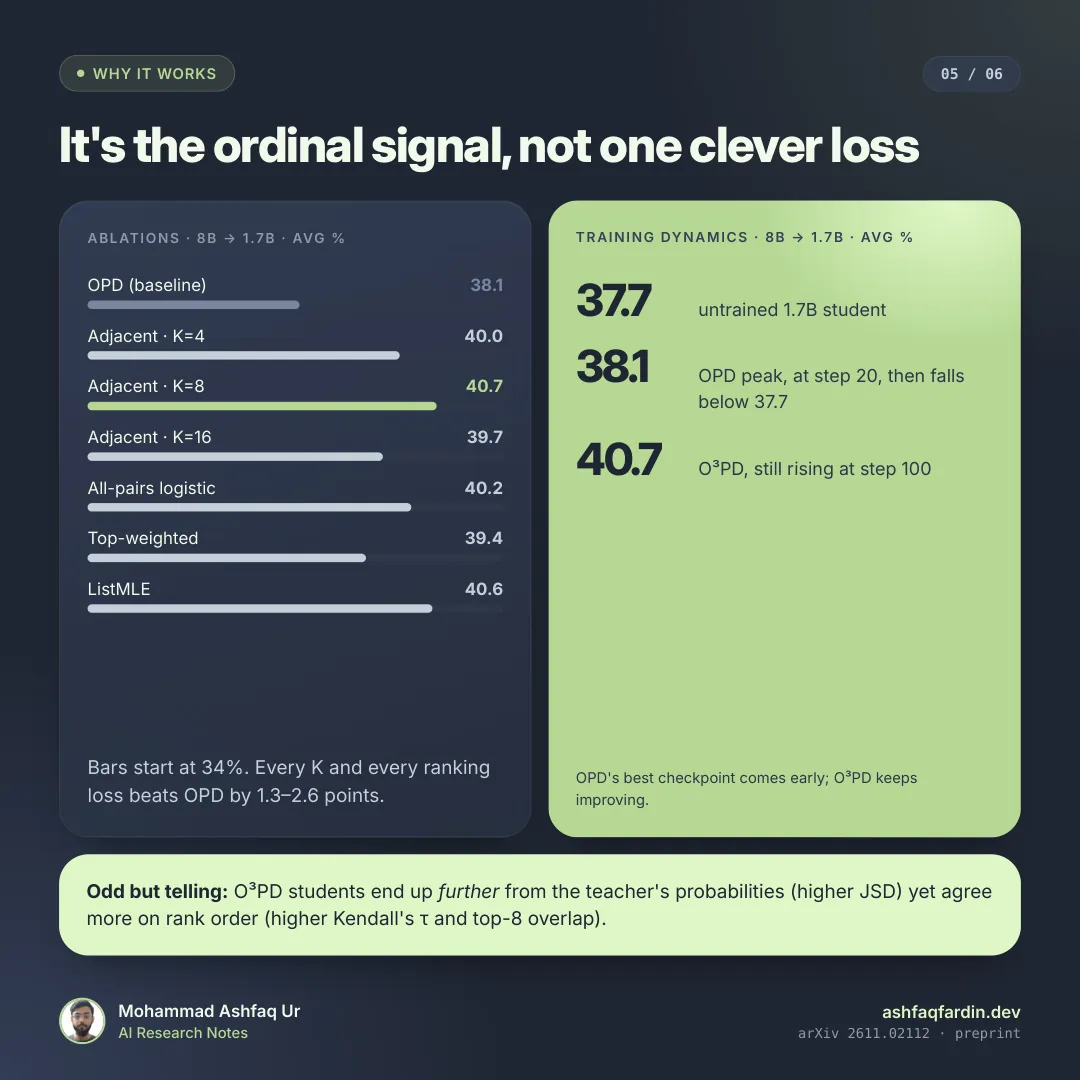
It's the ordinal signal, not one clever loss
ABLATIONS · 8B → 1.7B · AVG %
OPD (baseline) 38.1 Adjacent · K=4 40.0 Adjacent · K=8 40.7
Adjacent · K=16
39.7
All-pairs logistic
40.2 Top-weighted 39.4 ListMLE 40.6
Bars start at 34%. Every K and every ranking loss beats OPD by 1.3–2.6 points.
TRAINING DYNAMICS · 8B → 1.7B · AVG %
37.7
untrained 1.7B student
38.1
OPD peak, at step 20, then falls below 37.7
40.7
O³PD, still rising at step 100
OPD's best checkpoint comes early; O³PD keeps improving.
Odd but telling: O³PD students end up further from the teacher's probabilities (higher JSD) yet agree more on rank order (higher Kendall's τ and top-8 overlap).
Slide 6 · TAKEAWAY
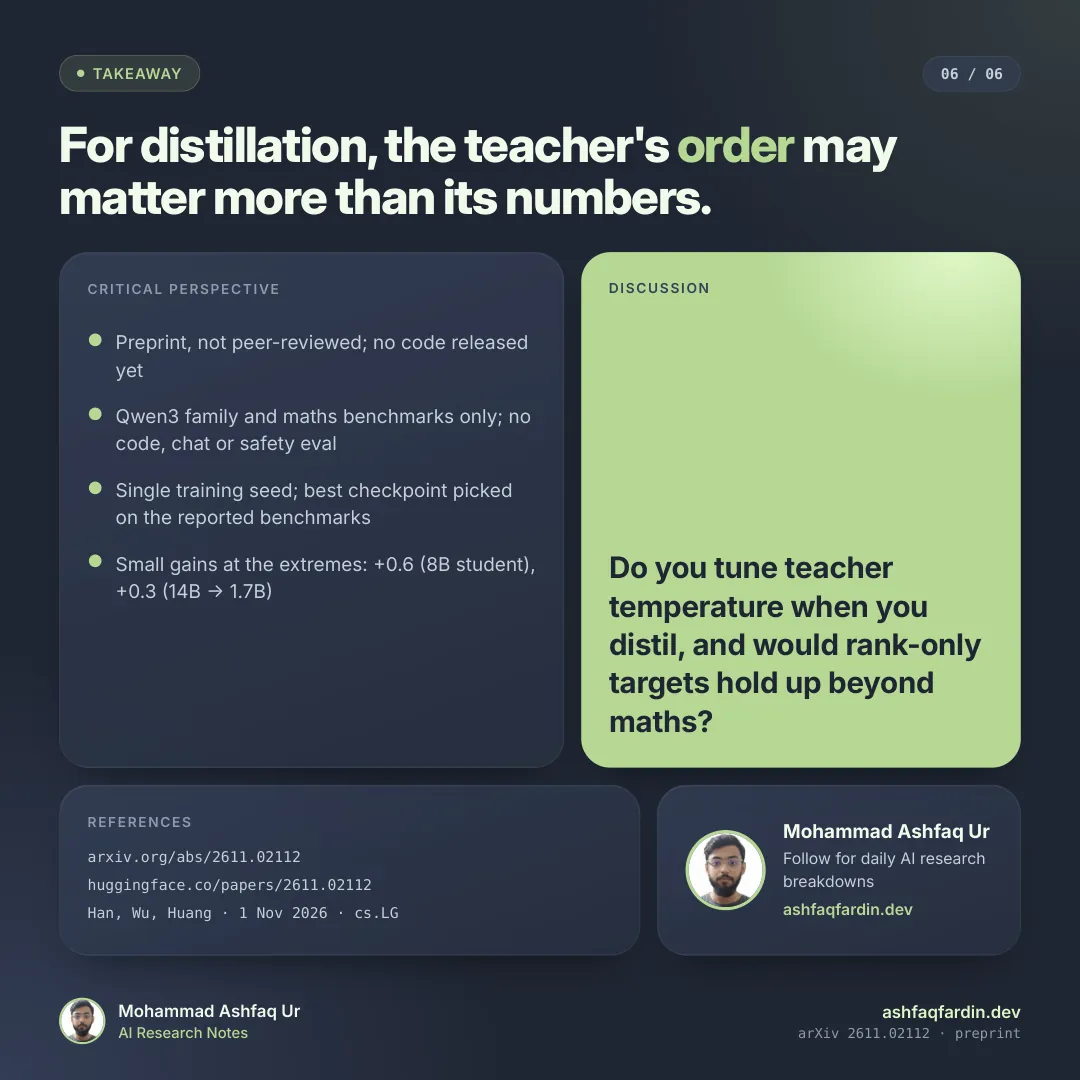
For distillation, the teacher's order may matter more than its numbers.
CRITICAL PERSPECTIVE
- Preprint, not peer-reviewed; no code released yet
- Qwen3 family and maths benchmarks only; no code, chat or safety eval
- Single training seed; best checkpoint picked on the reported benchmarks
- Small gains at the extremes: +0.6 (8B student), +0.3 (14B → 1.7B)
DISCUSSION
Do you tune teacher temperature when you distil, and would rank-only targets hold up beyond maths?
REFERENCES
arxiv.org/abs/2611.02112
huggingface.co/papers/2611.02112
Han, Wu, Huang · 1 Nov 2026 · cs.LG